Acceptance Criteria for Non-Deterministic AI Features
Given-When-Then carries a hidden assumption: that the same input produces the same output. When the feature is a model, that assumption quietly stops being true — and your acceptance criteria stop meaning anything.
Here is an acceptance criterion that has passed Refinement in a thousand teams:
Read it again and ask a simple question: who can execute this? Nobody can. The word accurately is carrying the entire criterion, and it is undefined. Two reasonable people will disagree about whether any given summary satisfies it, and there is no mechanism in the criterion to settle the disagreement.
The uncomfortable part is that this passed Refinement. It passed because it has the correct shape. Given, When, Then. Three clauses. It looks exactly like the acceptance criteria the team has written successfully for years, so nobody stopped it.
What changed is not the team's discipline. It is that Given-When-Then carries a hidden assumption, and that assumption has quietly stopped being true.
The Assumption Inside Given-When-Then
Conventional acceptance criteria assume determinism. Given input X, the system produces output Y. Run it again and you get Y again. Correctness is a property of a single execution, so pass and fail are meaningful words.
When the feature is a model, given input X the system produces something drawn from a distribution. Run it again and you get something different — and both results may be perfectly acceptable. Correctness is now a property of the distribution, not of any single run.
This is why teams write Gherkin for AI features and then quietly stop trusting it. The criteria are not wrong exactly. They are answering a question the system can no longer be asked.
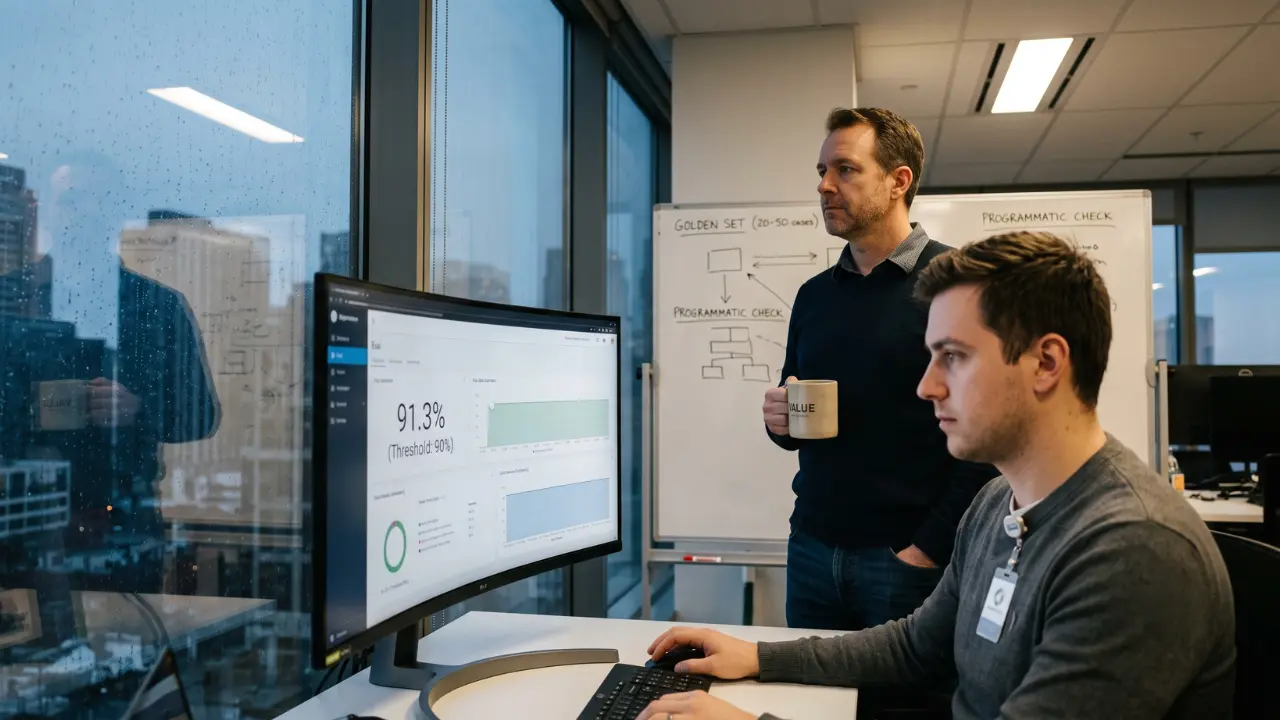
A unit test asserts one thing and returns pass or fail. An eval runs a hundred cases and returns 91%. Everything else in this article follows from that difference.
What an Eval Actually Is
The word comes from machine learning, where evaluation meant measuring a model against a held-out dataset. In practice today it means something more specific: a repeatable test of a probabilistic system's behaviour, scored across a set of cases rather than passed or failed on one.
Strip away the tooling and every eval, however sophisticated, is four things.
1. The dataset
A set of inputs, each with either a reference output or a rubric describing what good looks like. This is the golden set. It starts small and handmade — twenty to fifty cases is a legitimate beginning, not a compromise — and grows from real failures rather than from imagination.
2. The system under test
Not “the model.” The prompt, the model version, the retrieved context, and the tools it can call. All four are inputs, and a change to any of them changes behaviour. Teams that version only the prompt get blindsided when a provider updates a model underneath them.
3. The grader
How you decide whether a given output is acceptable. This is where the real design work lives, and it is covered below.
4. Aggregation and threshold
The scoring rule across the whole set. “At least 90% overall, and 100% on the safety subset” is an eval result. “It seemed to work in the demo” is not.
The Four Grader Types
Grader choice is what separates an eval that means something from an eval that produces a comforting number. Most real suites use several at once.
| Grader | Use it for | Fails when |
|---|---|---|
| Exact match | Classification labels, extracted field values, routing decisions | Output is free text — it rejects valid answers for being phrased differently |
| Programmatic check | Valid JSON, required fields, length limits, PII patterns, whether a cited ID exists | The property you care about is a matter of judgement |
| Model-graded (LLM-as-judge) | Faithfulness, tone, completeness, anything open-ended | The judge itself has never been calibrated against human grading |
| Human grading | Calibrating the judge, and continuous spot-checks | Used as the routine mechanism — too slow and expensive to run every Sprint |
Programmatic checks are the most underused of the four. A surprising proportion of what teams actually care about is deterministically checkable, and every property you can move into this category is one nobody has to argue about in a review. Before designing a rubric, ask what could simply be asserted.
Model-graded evals carry one obligation people skip. If a second model is scoring your outputs, you have to evaluate your evaluator. Have humans grade fifty cases, have the judge grade the same fifty, and measure the agreement. If the judge does not track human judgement, your 94% is a number about the judge and not about your product. This is the single most common reason a team reports excellent eval scores while users are visibly unhappy.
The Same Backlog Item, Rewritten
Return to the support ticket summariser. Here is what the acceptance criteria look like when they are eval-shaped.
This is testable. More importantly for a Scrum Team, it is negotiable — and that is where the conversation gets interesting.
The Threshold Is Scope, Not a Testing Detail
Moving that faithfulness threshold from 90% to 97% is not a small adjustment. It can be dramatically more work — better retrieval, a harder golden set, prompt iteration, sometimes a different model with different cost characteristics. It may not be achievable at all within the Sprint.
It is also, unavoidably, a statement about how much failure reaches users and what that failure costs them.
That makes the threshold a Product Owner decision, in exactly the same way that any other scope-versus-value trade-off is. It belongs in the same conversation as ordering the Product Backlog, not in a technical appendix written after Sprint Planning.
When the Developers pick the number alone — which is the default outcome if nobody intervenes — the team has allowed value to be defined by proxy, by the people best placed to judge feasibility and least placed to judge consequence. This is a recognisable Scrum failure mode wearing new clothes, and naming it as such tends to land quickly with experienced Product Owners.
“At 90%, one in ten summaries contains something the source does not support. Who sees those, and what happens when they do?” The Product Owner will usually have an answer, and the answer sets the threshold. If they do not have one, that is the finding.
Where the Scrum Master Actually Operates
You are not writing evals, and you should resist any pull toward becoming the person who does. Your work sits in three places.
Timing
Eval design must happen during Product Backlog refinement, not after the item is in a Sprint. If eval design keeps arriving mid-Sprint as a surprise, that is an impediment with a name and a pattern, and it belongs in a Sprint Retrospective rather than in a private conversation.
Sizing
Building the golden set is real work. It has to be visible in the Sprint Backlog and accounted for in the forecast. Teams that treat it as a testing afterthought discover at Sprint Review that it was never done, and that the feature therefore cannot be shown to meet its acceptance criteria. The Product Owner's guide to building a golden set covers how to size and grow one.
Ownership
Making sure the Product Owner owns the definition of good and the threshold — and does not delegate either by silence.
The Regression Loop
One habit is worth establishing early, because it costs almost nothing and compounds: every incident becomes a new eval case.
This is the same instinct as writing a failing test for a bug before fixing it, and framing it that way is how you get experienced developers to adopt it without argument. The golden set that matters after a year is not the one someone designed at the start. It is the one built from everything that actually went wrong.
It also creates the guard you need for the least obvious risk in the whole area — that a model version change, a prompt edit, or a shift in retrieved context can silently alter behaviour with no code diff to review.
Why This Matters Beyond the Feature
Acceptance criteria that cannot be executed do not prevent work from being accepted. They just move the decision somewhere invisible, where somebody decides on impression rather than evidence and nobody records that a decision was made.
That is precisely the mechanism by which verification debt accumulates. Untestable criteria are one of its most reliable sources, because they produce work that was formally accepted and substantively unexamined.
Nothing in this requires a change to Scrum. Refinement is still Refinement, the Product Owner still owns value, and the Developers still own the Increment. What has moved is the constraint: writing the feature is no longer the hard part, and deciding whether it is good enough is.
Read the Full Series
Acceptance criteria are one link in the chain that keeps AI-generated work honest. The Definition of Done sets the bar, the golden set makes “good” concrete, and verification debt is what accumulates when either one is skipped.
Frequently Asked Questions
What is an eval?
A repeatable test of a probabilistic system's behaviour, scored across a set of cases rather than passed or failed on a single run. It has four parts: a dataset, the system under test, a grader, and an aggregation threshold.
Can you still use Given-When-Then for AI features?
Yes, for the deterministic parts — output format, required fields, length limits, safety checks. The behavioural quality of a probabilistic feature cannot be expressed as a single pass or fail, so that part needs a scored eval with a threshold.
Who decides the pass threshold?
The Product Owner. The threshold determines how much work the feature requires and what level of failure reaches users, which makes it a value decision rather than a testing detail.
What is LLM-as-judge, and when should a team use it?
Using a second model to score outputs against a written rubric. It is appropriate for open-ended tasks where exact matching fails, but the judge must be calibrated against human grading on a sample before anyone trusts its scores.
How many cases does a golden set need?
Twenty to fifty real cases is a legitimate starting point. Size matters far less than whether the cases are real and whether the set grows from actual failures.
AI Scrum Master
Acceleration Course
An Interactive Hands-on course for Scrum Masters, Agile Coaches, and Agile Leaders
VIEW DETAILS